Bayes’ theorem is not Bayesian conditionalization

Today I taught Bayes’ rule and thought I would collect everything in a blog post. This post was written with the help of an LLM, based on the transcript of a recording.

Bayes’ rule is often introduced through elementary examples involving urns filled with colored balls. We know the composition of each urn, we draw a ball, and we ask how the observation changes the probability that the ball came from one urn rather than another.

In this setting, everything is straightforward. The experiment is specified in advance, all relevant probabilities can be interpreted as fractions of possible outcomes, and Bayes’ rule follows from the elementary laws of probability. The observation tells us something about the urn, but does not require us to reconsider the statistical model describing the experiment.

However, when we move from urns to the much more general problem of updating our beliefs in light of new evidence, something conceptually important happens. We are no longer simply calculating conditional probabilities within a fixed statistical model. We are prescribing how an observer should change their beliefs when new information becomes available.

These two problems look almost identical mathematically, but they are logically different.

Two statements that look the same

Let H denote a hypothesis and E an observation. Suppose that, before the observation, our beliefs are represented by a probability distribution P_0.

The usual formula reads

\displaystyle P_0(H|E)=\frac{P_0(E|H)P_0(H)}{P_0(E)}.

This is a mathematical identity. It follows directly from the definition of conditional probability, with the denominator computed, when necessary, using the law of total probability.

Notice, however, that all probabilities appearing in this formula belong to the same probability distribution, P_0.

Now suppose that we actually observe E, and denote by P_1 our new state of belief. The Bayesian prescription is

\displaystyle \boxed{P_1(H)=P_0(H|E).}

This is a different statement.

The first equation tells us what the conditional probability of H given E was before the observation. The second tells us what our probability for H should become after the observation.

Nothing in the elementary laws of probability requires these two quantities to coincide. Indeed, the laws of probability constrain a probability distribution at a given time, but do not, by themselves, prescribe how one probability distribution must evolve into another.

The step from the first equation to the second requires an additional principle of rational inference.

What if the observation changes our statistical model?

The distinction may seem artificial when we think about urns. It becomes much more natural when probabilities represent subjective degrees of belief.

Suppose that we are testing a scientific hypothesis using an instrument whose reliability we believe to be known. We observe a surprising result and update our beliefs about the hypothesis using Bayes’ rule.

But what if the result is so surprising that we begin to suspect that the instrument itself is malfunctioning?

In that case, the observation has done more than provide evidence about the original hypothesis. It has also led us to reconsider the statistical model, and in particular the probabilities describing the measurement apparatus.

An even more interesting situation arises when the observation suggests an entirely new hypothesis, one that we had not considered before.

A concrete example appears in a paper by Sylvia Wenmackers and Jan-Willem Romeijn, New Theory about Old Evidence: A Framework for Open-Minded Bayesianism (2016). They describe a food inspector who obtains five consecutive positive results from tests for Salmonella. Initially, the inspector considers only whether the restaurant follows proper hygiene procedures. However, the surprising sequence of results leads her to consider a third possibility: perhaps the testing strips themselves are contaminated.

The problem is no longer simply how to redistribute probabilities among the original hypotheses. The observation has changed the set of hypotheses under consideration.

Of course, if the possibility of a defective instrument had already been included in the original probabilistic model, ordinary Bayesian conditioning could account for it. But this observation does not eliminate the conceptual difficulty. A sufficiently rich model may anticipate many kinds of uncertainty, but the laws of probability alone do not tell us how to revise a model when a previously unconsidered possibility enters the picture.

In other words, Bayesian conditioning is a rule for updating beliefs within a specified probabilistic framework. The justification for applying it as a general rule of learning is a separate question.

Ramsey had already noticed this in 1926

This distinction had been formulated very explicitly already a century ago by Frank P. Ramsey, one of the founders of the subjective interpretation of probability.
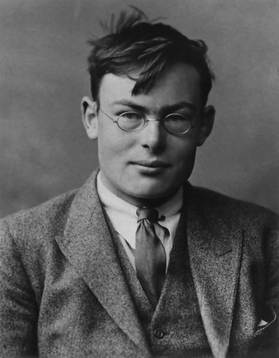
Frank Plumpton Ramsey (1903-1930)

In his celebrated essay Truth and Probability, written in 1926 and published posthumously in 1931, Ramsey carefully distinguishes the degree of belief in a proposition p conditional on q from the degree of belief that an individual would actually have in p after learning q.

His explanation is strikingly direct:

"knowledge of q might for psychological reasons profoundly alter his whole system of beliefs."

This is from page 180 of the original publication, which can be found in this electronic edition of Ramsey’s essay.

Ramsey was not suggesting that every psychological change of belief is rational. Rather, he was pointing out that conditional belief and actual belief revision are conceptually different things.

The question is therefore not whether an observation can change our beliefs in ways other than conditioning. Clearly, it can. The question is whether, and under what conditions, such changes are rationally justified.

When is Bayesian conditioning justified?

This question has an extensive history in the philosophy of probability, where the updating prescription is usually called the Principle of Conditionalization.

Richard Jeffrey, in Conditioning, Kinematics, and Exchangeability (1988), identifies two conditions under which ordinary conditioning is appropriate.
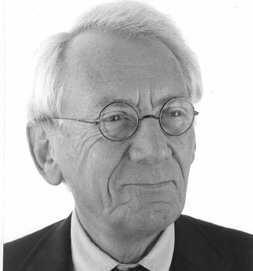
Richard Jeffrey (1926-2002)

The first is certainty: after the observation, the event E is regarded as certain,

\displaystyle P_1(E)=1.

The second is sufficiency: learning E does not change our conditional beliefs given E,

\displaystyle P_1(H|E)=P_0(H|E).

Together, these conditions imply the usual Bayesian updating rule.

The crucial point is that the second condition is not imposed by probability theory. It is an assumption about what the observation has, and has not, changed in our state of knowledge.

Jeffrey also developed a more general theory of updating, now known as Jeffrey conditionalization, which allows an observation to change probabilities without making any particular event certain. This theory was subsequently investigated in detail by Persi Diaconis and Sandy Zabell in their paper Updating Subjective Probability (1982).

Richard Bradley, in Radical Probabilism and Bayesian Conditioning (2005), goes even further, examining situations in which the observation changes conditional beliefs themselves.

Thus, the question of when conditioning is appropriate has been recognized for a long time, including within the Bayesian tradition itself.

Why should we follow Bayes’ rule, then?

Once we recognize that conditioning is an additional rule, rather than a mathematical identity, the natural question is how to justify it.

Several answers have been proposed.

One influential approach is based on consistency across time. David Lewis, in Why Conditionalize? (written in 1972 and published in 1999), develops a diachronic Dutch-book argument. Under appropriate assumptions about an agent’s betting dispositions and updating policy, deviating from conditionalization can expose the agent to a sequence of individually acceptable bets that together guarantee a loss.

Another approach is based on epistemic utility. In Justifying Conditionalization: Conditionalization Maximizes Expected Epistemic Utility (2006), Hilary Greaves and David Wallace show that, under specified conditions on epistemic utility, conditionalization is the unique updating rule that maximizes expected epistemic utility.

A third possibility is to invoke a principle of minimum change: when new information arrives, our beliefs should change only to the extent required to accommodate that information, and not more.

For example, suppose that P is our prior distribution and that the only new constraint is that an event E has become certain. Among all distributions R satisfying R(E)=1, we may select the one minimizing the relative entropy

\displaystyle D(R\|P).

For P(E)>0, this procedure uniquely selects

\displaystyle R=P(\cdot|E),

namely, ordinary Bayesian conditioning.

The argument extends naturally to Jeffrey updating when the new information specifies an updated marginal distribution rather than a certain event. I have discussed this construction in a separate note on this blog.

All these approaches have something important in common. They do not derive the Bayesian updating prescription from the elementary laws of probability alone. Instead, they identify additional requirements that select conditionalization as the appropriate rule.

Naturally, the strength of each justification depends on its assumptions. A minimum-change argument, for example, requires specifying what counts as a change and which revisions are admissible. A Dutch-book argument relies on assumptions about betting and intertemporal commitments. An epistemic-utility argument requires assumptions about how epistemic success is evaluated.

Such assumptions are not mathematical consequences of the product rule. They are precisely what gives an updating rule its normative content.

The difference matters

One might object that all this is unnecessarily complicated. After all, Bayes’ rule works extraordinarily well in statistical inference, machine learning, and countless scientific applications.

But its practical success should not obscure the logical distinction between a conditional probability and a prescription for changing beliefs.

The important point is not that Bayesian updating is wrong, nor that every possible reconsideration of a statistical model invalidates it. Rather, the point is that its status as a rule of rational inference requires a justification that goes beyond the elementary probability calculus.

This becomes particularly important when we attempt to generalize Bayesian reasoning beyond classical probability theory, as in quantum Bayesian retrodiction. In that setting, the problem is not merely to write down an analogue of a familiar formula, but to understand which requirements make one among the possible generalizations the appropriate rule of inference.

The lesson, however, is already present in the classical case.

Bayes’ theorem tells us how conditional probabilities are related. Bayesian conditionalization tells us how we should learn.

The former is a theorem of probability theory. The latter is a principle of rational inference.

Confusing the two risks making Bayesian updating appear either more trivial or more universal than its actual justification warrants.


References and further reading

Bayes’ rule and Jeffrey’s updating from the principle of minimum change

What follows is, to the best of my understanding, largely folklore. Variants of the argument appear implicitly across the literature on Bayesian updating, relative entropy, and consistent inference, and the conclusion is often taken for granted once one is familiar with Jeffrey updating. However, I have not been able to find a place where the reasoning is laid out explicitly and in a self-contained way, starting from minimal assumptions and making clear what is, and is not, being imposed. For that reason, I am recording this note here, both for my own reference and in the hope that it may be useful to others. A PDF version containing the same material, with slightly improved formatting, is available here.

Let XX and YY be finite-valued quantities (random variables) about which we wish to reason. Our prior information is summarized by a joint distribution

P(x,y)=p(x)φ(y|x),P(x,y)=p(x)\,\varphi(y|x),

where p(x)p(x) represents our prior state of knowledge about XX, and φ(y|x)\varphi(y|x) encodes the likelihood. No interpretation beyond this bookkeeping role is assumed.

From PP we may compute the implied marginal distribution PY(y)=∑xp(x)φ(y|x)P_Y(y)=\sum_x p(x)\,\varphi(y|x) and, by the product rule (I wouldn’t call this “Bayes’ theorem” yet), the inverse conditional distribution

φ^(x|y)=P(x|y)=p(x)φ(y|x)PY(y).\hat\varphi(x|y)=P(x|y)=\frac{p(x)\,\varphi(y|x)}{P_Y(y)}.

Now suppose that new information becomes available which does not specify a particular value of YY, but instead constrains our revised beliefs about YY to take the form of a probability distribution τ(y)\tau(y). The problem is then to determine what joint distribution R(x,y)R(x,y) should represent our new state of knowledge, given that it must be consistent with τ\tau and must not contain any information not logically implied by the prior PP together with this new constraint.

Principle of minimum change

Following the general principle that probabilities should be updated only to the extent required by new information, we select RR to minimize the relative entropy

D(R‖P)=∑x,yR(x,y)log⁡R(x,y)P(x,y),D(R\|P)=\sum_{x,y}R(x,y)\log\frac{R(x,y)}{P(x,y)},

subject to the constraint RY=τR_Y=\tau. This criterion ensures that no unwarranted assumptions are introduced.

Solution

Any admissible RR may be written as

R(x,y)=τ(y)R(x|y).R(x,y)=\tau(y)\,R(x|y).

Substitution into the relative entropy yields the identity

D(R‖P)=∑x,yR(x,y)log⁡R(x,y)P(x,y)={∑x,yτ(y)R(x|y)log⁡τ(y)P(y)+∑x,yτ(y)R(x|y)log⁡R(x|y)φ^(x|y)}=∑x,yτ(y)R(x|y)[log⁡τ(y)P(y)+log⁡R(x|y)φ^(x|y)]={∑x,yτ(y)R(x|y)log⁡τ(y)P(y)+∑x,yτ(y)R(x|y)log⁡R(x|y)φ^(x|y)}={∑x,yτ(y)R(x|y)log⁡τ(y)P(y)+∑x,yτ(y)R(x|y)log⁡R(x|y)φ^(x|y)}={∑x,yτ(y)R(x|y)log⁡τ(y)P(y)+∑x,yτ(y)R(x|y)log⁡R(x|y)φ^(x|y)}=D(τ‖PY)+∑x,yτ(y)R(x|y)log⁡R(x|y)φ^(x|y)={∑x,yτ(y)R(x|y)log⁡τ(y)P(y)+∑x,yτ(y)R(x|y)log⁡R(x|y)φ^(x|y)}=D(τ‖PY)+∑yτ(y)D(R(⋅|y)‖φ^(⋅|y)).={∑x,yτ(y)R(x|y)log⁡τ(y)P(y)+∑x,yτ(y)R(x|y)log⁡R(x|y)φ^(x|y)}\begin{aligned} D(R\| P) &= \sum_{x,y}R(x,y)\log\frac{R(x,y)}{P(x,y)} \\ &= \sum_{x,y}\tau(y)R(x|y)\left[\log\frac{\tau(y)}{P(y)}+\log\frac{R(x|y)}{\hat\varphi(x|y)}\right] \\ &= \left\{\sum_{x,y}\tau(y)R(x|y)\log\frac{\tau(y)}{P(y)}+\sum_{x,y}\tau(y)R(x|y)\log\frac{R(x|y)}{\hat\varphi(x|y)}\right\} \\ &= D(\tau\|P_Y)+\sum_{x,y}\tau(y)\;R(x|y)\;\log\frac{R(x|y)}{\hat\varphi(x|y)} \\ & = D(\tau\|P_Y) + \sum_y \tau(y)\; D\Big(R(\cdot|y)\|\hat\varphi(\cdot|y)\Big)\;. \end{aligned}

The first term depends only on the revised marginal τ\tau and is therefore fixed. The second term is nonnegative and vanishes if and only if

R(x|y)=φ^(x|y)for all x,y.R(x|y)=\hat\varphi(x|y) \quad\text{for all }x,y.

Hence the unique distribution consistent with the stated constraints and the principle of minimum updating is R(x,y)=τ(y)φ^(x|y)R(x,y)=\tau(y)\,\hat\varphi(x|y), wherever τ(y)>0\tau(y)>0. Note that, if it happens that τ(y)>0\tau(y)>0 but PY(y)=0P_Y(y)=0, we are in the situation in which the new evidence is falsifying our prior. This is signaled by the fact that, in this case, D(τ‖PY)=+∞D(\tau\|P_Y)=+\infty.

Interpretation

The new information alters only our beliefs about YY; therefore, rational consistency requires that our conditional beliefs about XX given YY remain exactly those implied by the prior. Any other choice would amount to smuggling in additional information not contained in the premises.

Excerpt from an Opinion Paper on the Future of Quantum Science and Technology

A few months ago I was invited by Prof. Miroljub Dugic (Institute of Physics, University of Kragujevac, Serbia) to take part in a poll on the future of quantum science and technology. Below I report the questions together with my answers. The complete paper can be downloaded from this link.

Do you find the quantum measurement problem worth striving?

I really have no idea if or how the quantum measurement problem may be solved. Quantum theory itself has nothing to say about a putative solution, so, if I must pick one, I would say that any genuine resolution of the measurement problem, if it exists at all, would have to come from new physics for which we currently have neither hints nor any operational need, in a sense. For the moment, the problem seems to tell us more about the limits of our preferred narratives than about the limits of formalism itself.

Which research directions do you find prominent in theory and applications?

I believe we should more decisively push toward an observer-dependent perspective, not only in quantum theory but in science as a whole, including cosmology. This idea is not new; it is as old as science itself. From time to time it resurfaces, and when it does it sheds new light on physics, yet it is quickly overshadowed again by the powerful illusion that we call “objective reality”. In this spirit, I expect research directions that put center stage what an observer can infer and learn, and how such inferences are constrained or enabled by physical theory, to become increasingly prominent. Such an approach may guide both theoretical developments and quantum technologies.

What would you expect of the future post-quantum theory?

If a future post-quantum theory ever emerges, to deserve that name, it would have to depart from quantum theory at least as radically as quantum theory departed from classical physics. It is worth recalling that the inadequacy of classical theory was made evident by relatively simple, low-energy experiments at the end of the nineteenth and the beginning of the twentieth century. By contrast, and this is an important methodological point, we currently have no experimentally demonstrated situations in which quantum theory is inadequate. The open issues we do have are conceptual or theoretical rather than empirical. The regimes where quantum theory might conceivably fail lie at extreme scales not yet accessible to experiment. Without concrete empirical hints, imagining a genuinely new framework becomes exceedingly difficult. In this sense, talk of a post-quantum theory today feels uncomfortably close to “armchair philosophizing”, carried out without the observational footholds that historically guided genuine theoretical revolutions.

What does “macroscopic” really mean in quantum theory?

One of the persistent difficulties in discussing the emergence of macroscopic irreversibility from microscopic quantum dynamics is that we often talk about “macroscopic states”, “macroscopic operations”, or “macroscopic correlations” without a fully satisfactory definition of what these terms actually mean.

This paper, written together with Teruaki Nagasawa, Eyuri Wakakuwa, and Kohtaro Kato, grew out of a very concrete problem related to the second law of thermodynamics. In earlier work, we showed that for an isolated quantum system the macroscopic entropy does not increase if and only if the system remains in a macroscopic state throughout its evolution. The problem was that, at that stage, “macroscopic state” was defined only implicitly. This made it hard to push the discussion further, because it was unclear what structural, algebraic, or operational features such states really had.

The goal of this work was therefore not to introduce yet another entropy, but to understand macroscopicity itself in a precise way. We wanted a definition that was algebraic, constructive, and operational, and that could serve as a solid foundation for discussing emergence.

Macroscopicity as an inferential boundary

One of the main messages of the paper is that the divide between “macro” and “micro” is not absolute. It depends on the observer. This statement should be taken in a very literal and modest sense.

By an observer we do not mean anything related to the measurement problem or consciousness. We simply mean a specification of which physical quantities can be simultaneously measured. These are what von Neumann already called macroscopic observables. Before discussing emergence, one must decide which variables one is actually focusing on.

Once this choice is made, the distinction between macroscopic and microscopic degrees of freedom coincides exactly with a boundary between what can be inferred and what cannot be inferred. Given the measured variables and some prior information, certain microscopic details can be retrodicted from macroscopic data, while others are irretrievably lost. What counts as macroscopic is determined by this inferential boundary. It is not that macroscopic variables “emerge” from microscopic ones that are “hidden” underneath. Rather, the choice of macroscopic variables determines what is macro and what is micro.

Interestingly, this inferential and retrodictive perspective was not imposed from the outside. It emerged naturally from the mathematics. In hindsight, this was quite telling, especially in light of recent work we did on the role of prediction and retrodiction in fluctuation relations.

From observational entropy to observational deficit

Observational entropy already captures part of this story. It explains how entropy can increase under unitary dynamics when one restricts attention to macroscopic measurements. However, in its standard formulation it relies on a uniform prior.

This is a serious limitation. In thermodynamic settings, a thermal prior is often the natural choice. In infinite-dimensional systems, the uniform state may not even exist. For this reason, we introduced the notion of observational deficit, defined relative to an arbitrary prior. Conceptually, the observational deficit measures how much information about a state is lost when one moves from a microscopic description to macroscopic data, taking into account the observer’s prior knowledge.

Macroscopic states are then precisely those for which this deficit vanishes. They are the states that can be perfectly retrodicted from macroscopic data alone.

Inferential reference frames and the MPPP

A central technical result of the paper is the existence and uniqueness of what we call the maximal projective post-processing (MPPP) of a measurement, relative to a given prior. This object plays a key conceptual role.

The result shows that any observer, defined by a measurement and a prior, can be represented by a suitable projective measurement. This projective measurement captures exactly the information that is inferentially accessible. For this reason, we interpret it as an inferential reference frame.

Just as a symmetry reference frame distinguishes between speakable and unspeakable information, an inferential reference frame distinguishes between what can be retrodicted from macroscopic data and what cannot. It is this structure then that decides what counts as macroscopic and what counts as microscopic for a given observer.

A resource theory of microscopicity

Once macroscopic states are clearly identified, it becomes natural to ask what makes one state more microscopic than another. Answering this question requires more than a classification. It requires an operational framework.

This is why we developed a resource theory of microscopicity. In this theory, macroscopic states are free states, and microscopicity is the resource. The framework forces one to think in terms of operations that do not generate microscopicity and to clarify what is really at stake when microscopic details matter.

An important outcome is that several well-known resource theories appear as special cases. Coherence, athermality, and asymmetry all fit naturally into this framework once appropriate choices of measurements and priors are made. Seeing these theories as instances of microscopicity provides a unified operational interpretation, and sheds light, for example, on the distinction between speakable and unspeakable coherence.

Observer-dependent correlations

The same perspective can be applied to correlations. Entanglement, discord, and related notions are often treated as absolute properties of states. Our results support a different view. The visibility and usefulness of correlations depend on the observer’s inferential reference frame.

Correlations are, after all, correlations among observers, so it is entirely natural to ask what it means for correlations themselves to be macroscopic. What matters is not an abstract, observer-independent property of a state, but which correlations are actually accessible given a specific inferential reference frame. From this perspective, it is natural to start from what correlations look like from the viewpoint of a single observer with limited access, since this already determines which inter-observer correlations can meaningfully be discussed. Our framework provides a starting point for such an analysis, and may eventually lead to something like a relativity theory for inferential reference frames.

What this enables

At a broad level, this work provides a rigorous solution to a basic mathematical problem: what does it mean for a state, an operation, or a correlation to be macroscopic?

Without a precise answer to this question, discussions of the emergence of macroscopic behavior risk remaining vague. With it, we can finally say what we are talking about. This does not solve the problem of emergence by itself, but it clarifies the language and the structure needed to address it in a meaningful way.

The paper is titled Macroscopicity and observational deficit in states, operations, and correlations and appeared in Reports on Progress in Physics earlier this year. It is available for free on the arXiv.

How do you update your quantum beliefs?

Bayes’ rule is often introduced in textbooks through examples involving urns filled with colored balls. It is striking, however, that the same formula works just as well in situations totally unrelated to urns or counting. In fact, Bayes’ rule applies also to how we update beliefs, learn from data, and draw inferences about the world. The fact that its success extends far beyond probability puzzles suggests that Bayes’ rule captures something fundamental about rational reasoning itself.

Indeed, there are several ways to justify Bayes’ rule as the only possible rule of consistent updating. De Finetti, Cox, Jeffreys, Jeffrey, and many other argued that, if an agent deviates from Bayes’ rule, they open themselves to “attacks” that would make them “lose” (money, time, resources, etc.) with probability one in the long run. However, all such approaches rely on axioms, and while some axioms may seem natural and acceptable to one researcher, they may not seem as convincing to another.

Interestingly, there exists however another way (similar to Jaynes’ maximum entropy principle, in fact) to justify Bayes’ rule: the principle of minimum change. When new data arrive, we should only revise our prior beliefs as much as needed to remain consistent with the new evidence. This is a conservative stance toward knowledge that avoids bias by preferring the smallest possible adjustment compatible with the facts.

In a work recently published on Physical Review Letters, together with Ge Bai and Valerio Scarani, we asked how this principle might extend to the quantum world. Quantum systems do not possess definite properties before measurement, and probabilities are replaced by density matrices that describe our partial knowledge of outcomes. Updating such knowledge is therefore not straightforward. What does it mean to change a quantum state “as little as possible” while incorporating new information?

To address this, we reformulated the minimum change principle directly at the level of quantum processes rather than their individual states. We used quantum fidelity to measure how similar two processes are and searched for the update that maximizes this similarity. The result turned out to coincide, in many important cases, with a well-known mathematical transformation in quantum information theory called the Petz recovery map.

This finding provides a new interpretation of the Petz map: it is not merely a technical tool, but rather, the natural quantum analogue of Bayes’ rule. Of all the possible updates, this one changes our quantum description in the smallest consistent way. This explains why, despite often being described as merely “pretty good,” the Petz map keeps reappearing in many different contexts. It has been independently rediscovered in quantum error correction, statistical mechanics, and even quantum gravity because it expresses the same logic that makes Bayes’ rule universal. It is not an approximation, but rather, the quantum form of rational inference itself.

The quantum version of Bayes’ rule does more than provide a new mathematical identity. It offers a systematic way to reason about quantum systems, to retrodict past states from observed data, and to quantify how much information about the past is lost over time. This connects directly to our previous studies on observational entropy and retrodictability, where the second law of thermodynamics emerges as a statement about the progressive loss of our ability to reconstruct the past.

Seen from this perspective, learning, inference, and even entropy growth are aspects of a single story about how information evolves. The quantum Bayes’ rule sits at the centre of that story, providing a bridge between classical reasoning and the probabilistic structure of quantum theory. A rule that is often illustrated with urns and balls finds a new form in quantum theory, where neither urns nor balls exist. This perhaps suggests that rational updating is not tied to any particular physical model (classical, quantum, etc.) but expresses a deeper logic of information itself.

Causal vs noncausal information revivals: a fresh take on quantum non-Markovianity

Two things have long bothered me about the way we discuss quantum non-Markovianity. First, that the concept fails to exclude classical processes, so that the use of the word “quantum” seems unjustified. Second, and related to the first but somewhat more puzzling, that a mere mixture of two Markovian processes can appear non-Markovian. Such a non-Markovianity surely shouldn’t be taken too seriously. This disconnect has persisted despite years of work, subtly undermining the foundations of our understanding.

In our new paper, Causal and Noncausal Revivals of Information: A New Regime of Non-Markovianity in Quantum Stochastic Processes, just published in PRX Quantum (open access) together with Rajeev Gangwar, Kaumudibikash Goswami, Himanshu Badhani, Tanmoy Pandit, Brij Mohan, Siddhartha Das, and Manabendra Nath Bera, we finally provide a satisfying resolution. By distinguishing between causal and noncausal information revivals, we create a conceptual and operational framework that clarifies what non-Markovianity in quantum systems really means.

The Puzzle of Mixtures and Backflows

Let’s begin with the basics. A process is Markovian if its future evolution depends only on the present state, not the past. In quantum dynamics, this notion gets murky when the system is not isolated but interacts with an environment. Textbooks typically assume that the system and its environment start uncorrelated: a neat assumption, but physically unrealistic. Initial correlations are inevitable, especially in strongly coupled systems. (In fact, the first post on this blog was about this very topic.)

This led to a long line of research investigating whether quantum channels can still describe the evolution of a subsystem even when initial correlations are present. While various conditions and formalisms were proposed (notably assignment maps and quantum discord), none satisfactorily addressed the oddity that a convex combination of Markovian processes can appear non-Markovian. This is particularly troubling if we hope to construct a resource theory of non-Markovianity, where convexity is essential.

Revivals Are Not Always Backflows

Our central insight is that information revivals, which we model as increases in the mutual information between a system and an ancillary reference after an interaction with the environment, can come in two flavors: causal and noncausal. Causal revivals correspond to genuine backflows of information from the environment to the system. Noncausal revivals, however, can be explained entirely using degrees of freedom that never interacted with the system at all.

This subtle distinction allows us to separate apparent non-Markovianity (which can be faked by a clever model with hidden correlations) from genuinely quantum non-Markovianity (which requires a true causal connection).

To formalize this, we bring in tools from quantum information theory: squashed entanglement, conditional mutual information, and Petz’s theory of statistical sufficiency. We prove that if a revival can be explained without violating the data-processing inequality for some inert extension (i.e., hidden, non-interacting degrees of freedom), then it is noncausal. In contrast, causal revivals must involve a flow of information from the environment.

Why This Matters

Distinguishing causal from noncausal revivals does more than just clean up conceptual confusion. It has direct implications for experiments and applications. For instance, we provide operational conditions, depending only on system observables, to detect genuine information backflow. This opens the door to device-independent verification of quantum memory effects.

Moreover, we show that anything that is not genuine non-Markovianity, thus including noncausal revivals, forms a convex set. In other words, if you take the convex mixture of processes without genuine non-Markovianity, you get another process without genuine non-Markovianity: genuine non-Markovianity, unlike conventional non-Markovianity, cannot simply be generated by classical randomization. This is a very welcome feature: convexity is a cornerstone of resource theories, and it means that we can now meaningfully talk about genuine non-Markovianity as a resource in quantum information processing.

Maxwell’s demon, quantum theory, and the second law: who’s really in charge?

It is often said that the paradox of “Maxwell’s demon” is resolved by including the thermodynamic costs of measurement and memory erasure. The common claim is that these costs offset the demon’s apparent violation of the second law of thermodynamics, thereby restoring its validity. The truth, however, is quite the opposite: the fact that the costs of measurement and erasure offset the demon’s violation is a consequence of assuming that the second law is valid in the first place. In other words, it is the assumption of the validity of the second law that forces this equilibrium, not the other way around!

This realization, which echoes the thesis of Earman and Norton, came while studying some not-so-recent-anymore but still quite influential papers on quantum feedback protocols in quantum thermodynamics. While the narrative there adhered to the usual folklore on the subject (i.e., that quantum feedback protocols obey the second law whenever the thermodynamic costs of measurement and erasure are properly accounted for), what we found instead was quite different: quantum theory is in fact completely independent of the second law of thermodynamics! And it couldn’t be otherwise, simply because quantum theory has no built-in thermodynamics. There is no “quantum bullet” to exorcise Maxwell’s demon. In fact, in our work we explicitly constructed a model of a measurement and feedback process that violates the bounds required by the second law, even after including all costs (i.e., measurement and erasure costs) in the thermodynamic balance.

However, we also found that although quantum theory can violate the second law, it does not need to: any quantum process can be realized in a way that does not violate the second law of thermodynamics, simply by adding more systems (bath, battery, and so on) until the thermodynamic balance is restored.

There are two main takeaways from this story. First, even in quantum theory, it is the second law that guarantees the balance between gains and costs in feedback protocols, not the other way around. Second, although quantum theory and the second law of thermodynamics are logically independent, they can peacefully coexist. The second law of thermodynamics does not impose any hard constraints on what can be achieved in quantum theory: there is always a way to ensure compliance with the second law.

In conclusion, by no means can we claim that quantum theory is “demon-proof” by design. However, we now have a much clearer understanding of how quantum feedback protocols work, what they can and cannot do. The paper appeared today on npj Quantum Information but I like the look of the arXiv version better.

Quantum theory can exorcise Laplace’s demon. But Maxwell’s demon is still lurking…

Generalizing Observational Entropy for Complex Systems

Work in collaboration with Ge Bai and Valerio Scarani (NUS, Singapore), Dom Šafránek (IBS, Korea) and Joe Schindler (UAB, Spain), published today on Quantum.

In his 1932 book, von Neumann not only introduced the now familiar von Neumann entropy, but also discussed another entropic quantity that he called “macroscopic”. He argued that this macroscopic entropy, rather than the von Neumann entropy, is the key measure for understanding thermodynamic systems. Here we revisit and extend a concept derived from von Neumann’s macroscopic entropy, observational entropy (OE) — an information-theoretic quantity that measures both the intrinsic uncertainty of a system and the additional uncertainty introduced by the measurement we use to observe it.

Typically, the definition of OE assumes a “uniform prior,” i.e., it starts with an assumption of maximum uncertainty about the state of the system. However, this assumption is not always tenable, especially in more complex systems, such as those influenced by energy constraints or infinite dimensional systems, where instead other priors, such as the Gibbs distribution, would be preferable, both physically and mathematically.

Measurement is our window to the microscopic world, but it’s like a stained glass window: what’s on the other side looks distorted and coarse-grained. That’s where the second law comes in.

To fill this gap and extend OE to arbitrary priors, we first show how OE can be interpreted in two ways: as a measure of how much a measurement scrambles the true state of a system (statistical deficiency), and as the difficulty of inferring the original state from the measurement results (irretrodictability). These two aspects provide complementary insights into how much we lose or gain in our knowledge of the original state of a system when we make observations on it.

This conceptual insight leads us to introduce three generalized versions of OE: two that capture either statistical deficiency or irretrodictability, but are inherently incompatible; and a third, based on Belavkin-Staszewski relative entropy, that instead is able to combine both perspectives and provide a unified view of commuting and non-commuting priors alike. We expect that our results will pave the way for a consistent treatment of the second law of thermodynamics and fluctuation relations in fully quantum scenarios. From the abstract:

Observational entropy captures both the intrinsic uncertainty of a thermodynamic state and the lack of knowledge due to coarse-graining. We demonstrate two interpretations of observational entropy, one as the statistical deficiency resulting from a measurement, the other as the difficulty of inferring the input state from the measurement statistics by quantum Bayesian retrodiction. These interpretations show that the observational entropy implicitly includes a uniform reference prior. Since the uniform prior cannot be used when the system is infinite-dimensional or otherwise energy-constrained, we propose generalizations by replacing the uniform prior with arbitrary quantum states that may not even commute with the state of the system. We propose three candidates for this generalization, discuss their properties, and show that one of them gives a unified expression that relates both interpretations.

Tim Maudlin about the Gibbsian approach

Tim Maudlin here is talking about the Gibbsian approach to explain the second law of thermodynamics. He introduces the “coarse-graining” procedure, but then adds “but what the hell is going on here? how do you think about these interventions?

Here is the answer: the observer makes an inference based on what they can see about the system. That’s it. The second law is about the inferential process of the observer, not about the underlying physics. We have written about this in a few papers, and I have given several talks on this idea. It all makes perfect sense to me!